24  TMLE and Doubly Robust Estimation

Status: Draft

v0.5

24.1 Introduction

Targeted Maximum Likelihood Estimation (TMLE) is a semiparametric estimator with double-robustness properties under the relevant regularity and nuisance-model conditions (Laan and Rubin 2006; Laan and Rose 2011; Schuler and Rose 2017). Here TMLE is treated as a method for Seeing in the Observable role: it learns from recorded data while keeping the estimand, identification assumptions, observation model, and estimator distinct.

24.2 What Is TMLE?

TMLE is a semiparametric efficient, double robust estimator that:

  • Targets the causal parameter of interest
  • Uses machine learning for flexible models
  • Provides valid inference (confidence intervals, hypothesis tests)
  • Handles complex data (high-dimensional confounders, missing data)

24.2.1 Advantages

  • Double robust: Consistent if either outcome or treatment model is correct
  • Semiparametric efficient: Optimal variance among regular asymptotically linear estimators
  • Machine learning compatible: Can use Super Learner, neural networks, etc.
  • Valid inference: Confidence intervals and hypothesis tests

TMLE is one route to Neyman-orthogonal, double-robust estimation with flexible nuisance models. The econometric sibling is double/debiased machine learning (DML): cross-fitting plus orthogonal scores for average effects under high-dimensional or nonparametric nuisances (Chernozhukov et al. 2018, 2024). This chapter stays with TMLE and the LMTP bridge; for the DML presentation of the same orthogonalisation idea (partially linear and interactive regression scores rather than a targeted fluctuation step), see (Chernozhukov et al. 2024, Ch. 9).

24.3 TMLE Algorithm

Steps:

  1. Fit initial outcome model: Estimate \(Q_0(A, L) = E[Y \mid A, L]\) using flexible methods (e.g., Super Learner (Laan et al. 2007))
  2. Fit treatment model: Estimate \(g_0(A \mid L) = P(A \mid L)\) for weights
  3. Targeted update: Update the outcome model to target the treatment effect:
  • Compute “clever covariate” \(H(A, L) = \frac{\mathbb{1}(A=a)}{g_0(A \mid L)}\)
  • Fit a logistic regression: \(\text{logit}(Q_1(A, L)) = \text{logit}(Q_0(A, L)) + \epsilon H(A, L)\)
  • Update: \(Q_1(A, L) = \operatorname{expit}\{\operatorname{logit}(Q_0(A, L)) + \epsilon H(A, L)\}\)
  1. Compute effect: Estimate treatment effect from updated model
  2. Inference: Compute standard errors and confidence intervals

24.3.1 TMLE with missing outcomes

Suppose treatment \(A\) and baseline covariates \(L\) are observed for everyone, but outcome \(Y\) is recorded only when \(R_Y=1\). In addition to consistency and conditional treatment exchangeability, assume \(Y\perp R_Y\mid A,L\) and positivity of both treatment and outcome recording. Define the outcome regression \(Q(A,L)=E[Y\mid A,L,R_Y=1]\), treatment probability \(g_A(a\mid L)\) and response probability \(g_R(1\mid A,L)\). For the intervention mean under \(do(A=a)\), the targeting covariate becomes

\[ H_a(A,L,R_Y)= \frac{\mathbb{1}(A=a)R_Y} {g_A(a\mid L)\,g_R(1\mid A,L)}. \]

Fit and target the outcome regression using recorded outcomes, then average the updated predictions under each treatment over the baseline covariates of the whole cohort (Gruber and Laan 2012). For this standard construction, consistency is obtained if the outcome regression is consistently estimated, or if both treatment and response probabilities are consistently estimated, subject to the relevant regularity conditions. Valid confidence intervals additionally require control of the nuisance-estimation remainder and an appropriate variance estimate.

This is not an arbitrary two-of-three robustness guarantee. Nor does TMLE remove the need for positivity: if a relevant stratum never receives a treatment or never has its outcome recorded, the corresponding mean cannot generally be learned without extrapolation or further assumptions. Near-zero probabilities require diagnostics and sensitivity to weight truncation or a revised target (Petersen et al. 2012). Missing exposures or confounders require their own observed-data identification argument and a compatible imputation or estimation strategy (Dashti et al. 2024; Zhang et al. 2016).

24.3.2 Implementation: TMLE with TMLE.jl

The following example uses TMLE.jl to estimate a causal effect:

# Find project root and include ensure_packages.jl
project_root = let
    current = pwd()
    while !isfile(joinpath(current, "Project.toml")) && !isfile(joinpath(current, "_quarto.yml"))
        parent = dirname(current)
        parent == current && break
        current = parent
    end
    current
end
include(joinpath(dirname(Base.active_project()), "scripts", "book_bootstrap.jl"))
include(joinpath(dirname(Base.active_project()), "scripts", "biological_showcases.jl"))

@auto_using TMLE Random Distributions MLJLinearModels MLJModels DataFrames CategoricalArrays CairoMakie Statistics StableRNGs

# Observational cohort: nutrition confounds treatment and worm burden (Ch. 05b DGP)
cohort_raw = confounded_cohort_dgp(; n = 500, rng = StableRNG(42))
df = cohort_for_tmle(cohort_raw)
nutrition = df.nutrition
worm_burden = df.worm_burden

# Step 1: Define the estimand (what we want to estimate)
# ATE: average effect of treatment on worm burden adjusting for nutrition
Ψ = ATE(
    outcome = :worm_burden,
    treatment_values = (treatment = (case = 1.0, control = 0.0),),
    treatment_confounders = (treatment = [:nutrition],)
)

# Step 2: Define models for outcome and treatment
models = Dict(
    :worm_burden => with_encoder(LinearRegressor()),
    :treatment => with_encoder(LogisticClassifier(lambda = 0)),
)

# Step 3: Create TMLE estimator
tmle = Tmle(models = models)

# Step 4: Estimate the ATE
tmle_result, cache = tmle(Ψ, df; verbosity = 0)

# Step 5: Extract ATE results
ATE_estimate = estimate(tmle_result)
ATE_CI = confint(OneSampleZTest(tmle_result))
ATE_pvalue = pvalue(OneSampleZTest(tmle_result))

# Step 6: Compute counterfactual means separately for visualization
# E[Y | do(A=1)] and E[Y | do(A=0)]
Ψ_A1 = CM(
    outcome = :worm_burden,
    treatment_values = (treatment = 1.0,),
    treatment_confounders = (treatment = [:nutrition],)
)
Ψ_A0 = CM(
    outcome = :worm_burden,
    treatment_values = (treatment = 0.0,),
    treatment_confounders = (treatment = [:nutrition],)
)

cm_A1_result, cache = tmle(Ψ_A1, df; cache = cache, verbosity = 0)
cm_A0_result, cache = tmle(Ψ_A0, df; cache = cache, verbosity = 0)

E_Y_A1 = estimate(cm_A1_result)  # E[Y | do(A=1)]
E_Y_A0 = estimate(cm_A0_result)  # E[Y | do(A=0)]

# Standard error from confidence interval
# SE = (upper - lower) / (2 * z_alpha/2) where z_0.025 ≈ 1.96
se_ATE = (ATE_CI[2] - ATE_CI[1]) / (2 * 1.96)

# Compute naive estimate for comparison
treatment_numeric = [x == 1.0 ? 1 : 0 for x in df.treatment]
naive_ATE = mean(worm_burden[treatment_numeric .== 1]) - mean(worm_burden[treatment_numeric .== 0])

println("TMLE Results (treatment → worm burden, adjust nutrition):")
println("  E[W | do(T=1)] = ", round(E_Y_A1, digits=3))
println("  E[W | do(T=0)] = ", round(E_Y_A0, digits=3))
println("  ATE = ", round(ATE_estimate, digits=3))
println("  95% CI: ", ATE_CI)
println("  p-value: ", round(ATE_pvalue, digits=4))
println("\nComparison:")
println("  Naive estimate (ignoring confounding): ", round(naive_ATE, digits=3))
println("  TMLE estimate (adjusted): ", round(ATE_estimate, digits=3))
println("  Structural coefficient on continuous treatment scale: 0.7")
TMLE Results (treatment → worm burden, adjust nutrition):
  E[W | do(T=1)] = 0.093
  E[W | do(T=0)] = -0.305
  ATE = 0.4
  95% CI: (0.2821222823000251, 0.518097348794098)
  p-value: 0.0

Comparison:
  Naive estimate (ignoring confounding): 1.748
  TMLE estimate (adjusted): 0.4
  Structural coefficient on continuous treatment scale: 0.7
Figure 24.1: TMLE using TMLE.jl package for robust causal effect estimation

24.3.3 Choosing Between Methods

G-computation is preferred when:

  • Outcome models are well-understood
  • Full distribution is needed
  • Treatment strategies are complex

MSMs (IPTW) are preferred when:

  • Treatment model is well-understood
  • Simple marginal effects are sufficient
  • Implementation simplicity is important

When several outcomes share units and clusters (farms, herds), prefer CausalTargeted run_repeated_outcome_msm / run_parametric_repeated_msm with optional cluster= for the sandwich; that is sampling hierarchy on the IF, not an LMM (Ch. 28).

TMLE is preferred when:

  • Robustness to model misspecification is critical
  • Semiparametric efficiency is desired
  • Valid inference (confidence intervals) is needed

24.3.4 AgeSCM: propensity and IPTW for transport (not ATE on age)

Case Study 3 uses TMLE.jl alignment for domain propensity, not a targeted ATE on mosquito age. The estimand is predictive transport (E1): MAE when a whole country is held out.

  1. Nuisance design L: replica, dates, species, experiment, rearing, status, excluding country from L when fitting P(C | L), so propensity is not trivially saturated by the hold-out label.
  2. Stabilisation: weights use full-cohort P(C*) rather than train-only marginals.
  3. Schemes T0–T4: unweighted; marginal IPTW; adjusted IPTW (T2); trimmed weights (T3); target-domain reweight (T4).

On 73,521 spectra (full LOSO), T2 adjusted IPTW reduced pooled MAE for mean spectrum OLS from 23.73 to 22.87 days. This implements the weighting step familiar from MSM/TMLE workflows (Section 10.7) while the age head remains OLS or Flux+OLS in AgeSCM. Full doubly robust targeting of a scalar age estimand on ẑ is deferred to the GraphPPL/RxInfer head (Ch 30). When spectra enter the owned stack, compress them with CausalDynamics RepresentationSpec / encode_to_panel first so mediation and LMTP see code columns, not raw tensors (Ch. 30; CausalMediation methods).

24.4 Continuous exposures and LMTP

Binary ATE TMLE (above) is the right pedagogy for deterministic \(do(A=a)\). For continuous or multi-valued exposures, deterministic interventions often lack scientific interest and worsen positivity violations. Longitudinal modified treatment policies (LMTP) shift the natural value of treatment (e.g. raise exposure by one standardised unit subject to clamps) and admit cross-fitted TMLE / sequentially doubly robust estimators (Díaz et al. 2023; Díaz Muñoz and Laan 2012).

Conceptually, identification of the estimand precedes estimation. In this book’s examples, identification certificates come from CausalDynamics; continuous MTP (non-mediated) grids use CausalTargeted (run_lmtp_grid, recommend_run_options), including fold-stable encoding of mixed-type baselines; factor recodes of a finite \(A\) use run_discrete_lmtp or sequential policies (Policy Evaluation). Mediation uses CausalMediation (run_mediation, run_mediation_grid) with the same fold-stable CovariateSchema and optional intermediate confounders (moc) (Díaz and Hejazi 2020; Liu et al. 2024). Interventional TE / NDE / NIE also admit a recode MTP on factor \(A\) with continuous \(M\) (DiscreteTreatmentPolicy on both MediationSpec arms; run_mediation_grid stays numeric). Keep TMLE.jl for tabular binary ATEs; reach for LMTP when the estimand is a continuous-shift total-effect curve, for discrete-time event-free probability under MTP when the outcome is survival / event-time (SurvivalPolicy; (Díaz et al. 2024); same chapter), and for CausalMediation when the estimand is a mediated contrast.

TipSmall-n checklist (CausalTargeted)

For continuous MTP and mediation with tens to low hundreds of units (Díaz et al. 2023; Laan and Rose 2011):

  1. Start from recommend_run_options(n; engine, n_mediators) (lean Super Learner when \(n < 80\); parallel=false by default).
  2. Pass mixed-type baselines as-is (String / Bool / categorical are encoded with a fold-stable CovariateSchema in LMTP, sequential, survival, and mediation grids).
  3. Inspect positivity / support (positivity_report or grid positivity=true) (Petersen et al. 2012).
  4. For mediation, sweep nested MC (mediation_n_mc_sweep) until signs and SEs stabilise (Liu et al. 2024).
  5. Report tipping-point / partial-\(R^2\) sensitivity (sensitivity_report) (Cinelli and Hazlett 2020).
  6. Treat discovery graphs as sensitivity only (merge_discovery_sensitivity!), never as silent DAG replacement.

Package prose and DOIs: CausalTargeted methods · references. Worked δ-grid: Chapter 23 (Policy Evaluation).

24.4.1 Certificate → mediation estimate

The stack’s advantage is a typed hand-off. Build a small DAG, identify a MediationQuery, draw the same graph with DAGMakie, then convert the certificate into a MediationSpec and estimate.

project_root = let
    current = pwd()
    while !isfile(joinpath(current, "Project.toml")) && !isfile(joinpath(current, "_quarto.yml"))
        parent = dirname(current)
        parent == current && break
        current = parent
    end
    current
end
include(joinpath(project_root, "scripts", "ensure_packages.jl"))
@auto_using CausalDynamics CausalMediation Graphs

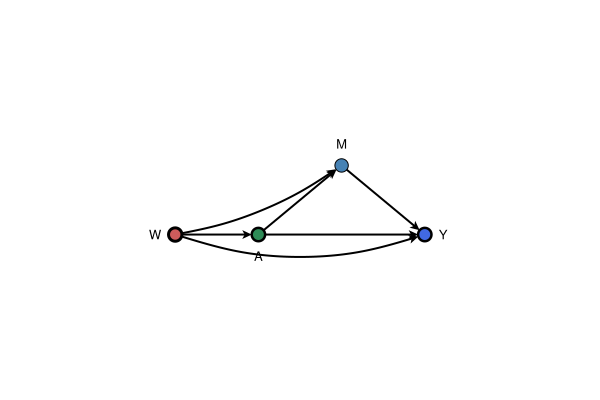
# W → A → M → Y, with A → Y and W → {M,Y}
# Qualify identify: TMLE.jl (earlier in this chapter) also exports identify.
g_med = DiGraph(4)
add_edge!(g_med, 1, 2); add_edge!(g_med, 1, 3); add_edge!(g_med, 1, 4)
add_edge!(g_med, 2, 3); add_edge!(g_med, 2, 4); add_edge!(g_med, 3, 4)
names_med = Dict(1 => :W, 2 => :A, 3 => :M, 4 => :Y)
id_med = CausalDynamics.identify(
    g_med, CausalDynamics.MediationQuery(:A, :Y, [:M]; effect_kind = :interventional);
    node_names = names_med,
)
println("strategy = ", id_med.strategy,
    "; adjustment = ", id_med.adjustment,
    "; mediators = ", id_med.mediators,
    "; moc = ", id_med.moc)
strategy = mediation_interventional; adjustment = [:W]; mediators = [:M]; moc = Symbol[]
Figure 24.2: Mediation identification DAG (Cinelli et al. good-control pattern (Cinelli et al. 2024)): baseline \(W\) is the good control; mediator \(M\) is elevated and is not adjusted. Identification and estimation share the same node roles.
@auto_using CausalMediation CausalTargeted DataFrames StableRNGs

df_med, truth_med = simulate_continuous_mtp_mediation(100; rng = StableRNG(20))
spec_med = spec_from_identification(id_med)
med_res = run_mediation(
    spec_med, df_med;
    deltas = [-0.5, 0.0, 0.5],
    folds = 2,
    n_mc = 8,
    estimator = :onestep,
    learners = DEFAULT_SL_LEARNERS,
    parallel = false,
    rng = StableRNG(21),
)
med_grid = med_res.table
nde = only(filter(r -> r.estimand == "NDE" && isapprox(r.delta, 0.5), eachrow(med_grid))).est
nie = only(filter(r -> r.estimand == "NIE" && isapprox(r.delta, 0.5), eachrow(med_grid))).est
eff = truth_med.effects(0.5)  # nominal δ in SD units (inactive clamp ≈ δ)
println("Mediation grid (δ = 0.5): NDE ≈ ", round(nde; digits = 3),
    ", NIE ≈ ", round(nie; digits = 3))
println("Oracle (approx.): NDE = ", round(eff.nde; digits = 3),
    ", NIE = ", round(eff.nie; digits = 3))
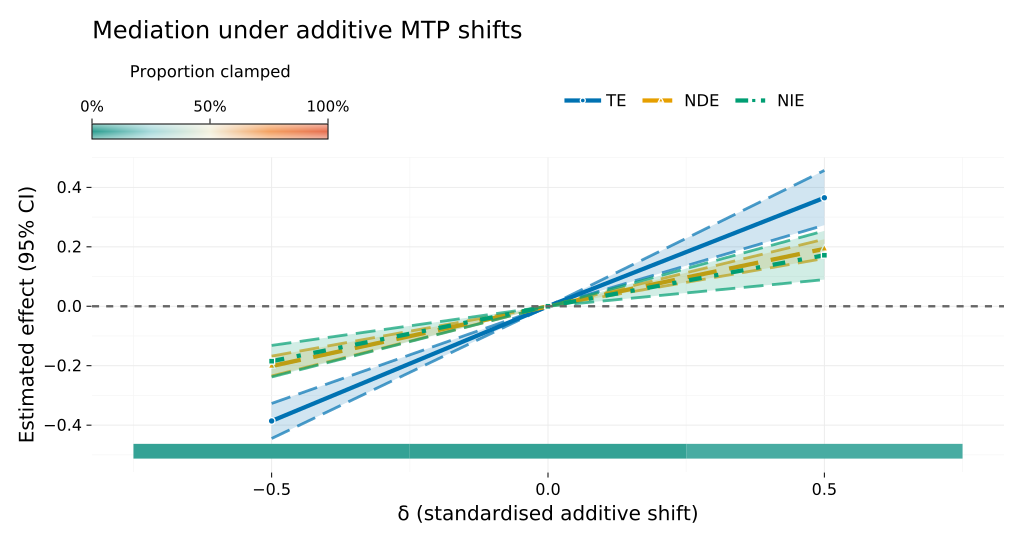
Mediation grid (δ = 0.5): NDE ≈ 0.193, NIE ≈ 0.172
Oracle (approx.): NDE = 0.175, NIE = 0.192
Figure 24.3: Interventional mediation TE / NDE / NIE curves under MTP shifts (run_mediation → plot_mtp_curve). (Díaz and Hejazi 2020; Liu et al. 2024)

Figure 24.3 shows the same certificate-driven grid with TE, NDE, and NIE on one axis; clamp strips appear when the grid carries a clamp column.

A factor recode of \(A\) (string levels, continuous \(M\)) is a one-contrast interventional decomposition, not a δ-grid:

@auto_using CausalMediation CausalTargeted DataFrames StableRNGs

df_cam, truth_cam = simulate_categorical_a_mediation(200; rng = StableRNG(61))
spec_cam = MediationSpec(
    :A, :Y;
    mediators = [:M],
    covariates = [:W],
    policy_d0 = discrete_recode_policy(Dict{String, String}()),
    policy_d1 = discrete_recode_policy(truth_cam.recode),
)
res_cam = run_mediation(
    spec_cam, df_cam;
    folds = 2, n_mc = 8, estimator = :onestep,
    learners = DEFAULT_SL_LEARNERS, rng = StableRNG(62),
)
d_cam = CausalMediation.decompose(res_cam)
println("Factor-A mediation TE ≈ ", round(d_cam.te; digits = 3),
    " (oracle ", round(truth_cam.te; digits = 3), ")")
Factor-A mediation TE ≈ 0.489 (oracle 0.11)

Natural / organic / recanting-twin families and nonempty moc remain numeric-\(A\) only.

Controlled direct effects answer a different question: they set the mediator to a specified value in both treatment arms (VanderWeele 2015). CausalMediation estimates these contrasts by outcome-regression standardisation (ControlledDirect, estimator = :plugin), currently with empty moc. It rejects one-step and TMLE requests for this path; a point intervention on a continuous mediator does not inherit the interventional-mediation EIF. Standard errors and confidence limits remain unavailable until an appropriate inference procedure is supplied. Outcome IPCW enters the supported mediation summaries under the declared MAR assumptions.

For \(M=A+\varepsilon_M\) and \(Y=A+M\), setting \(M=0\) in both treatment arms gives a controlled direct effect of one:

@auto_using CausalMediation DataFrames StableRNGs

cde_rng = StableRNG(65)
A_cde = Float64.(rand(cde_rng, 200) .< 0.5)
M_cde = A_cde .+ randn(cde_rng, 200)
df_cde = DataFrame(A = A_cde, M = M_cde, Y = A_cde .+ M_cde)
cde_table = run_mediation_scalar(
    df_cde, :A, :Y;
    mediators = [:M], covar = Symbol[],
    effect = ControlledDirect(:M => 0.0), estimator = :plugin,
    learners = (:glm,), folds = 2, rng = StableRNG(66),
)
cde_table[cde_table.effect .== "CDE", :]
1×5 DataFrame
Row se upper effect estimate lower
Float64 Float64 String Float64 Float64
1 NaN NaN CDE 1.0 NaN

Non-mediated continuous MTP total effects use the same identification idea but a different estimator: CausalTargeted run_lmtp_grid in Policy Evaluation (@fig-lmtp-mtp-grid). Soft façades that still live on CausalTargeted forward to CausalMediation when that package is loaded.

24.5 Stratum context

TMLE estimates causal functionals from recorded data under declared structural intervention assumptions, while keeping the observation process and estimand explicit.

24.6 Key Takeaways

  1. TMLE is double robust and semiparametric efficient
  2. TMLE algorithm combines outcome and treatment models with targeted update
  3. TMLE is preferred when robustness and valid inference are critical
  4. TMLE bridges Observable (data) and Structural (interventions)
  5. Continuous / longitudinal / event-time MTPs (total effects and survival) use CausalTargeted.jl (Ch. 23); mediation uses CausalMediation.jl with certificates from CausalDynamics (numeric MTP or factor-\(A\) recodes with continuous \(M\))

24.7 Further Reading

  • Laan and Rubin (2006): “Targeted maximum likelihood learning”
  • Laan and Rose (2011): “Targeted learning”
  • Schuler and Rose (2017): “Targeted learning in R”
  • Chernozhukov et al. (2018): Double/debiased machine learning for treatment and structural parameters
  • Chernozhukov et al. (2024): Applied Causal Inference Powered by ML and AI, Chapter 9 (generic DML; Double Lasso precursor in Ch. 4)
  • Díaz et al. (2023): Nonparametric causal effects based on longitudinal modified treatment policies
  • Díaz et al. (2024): Causal survival analysis under competing risks using LMTP (thin event-time path in Ch. 23)
  • Díaz and Hejazi (2020): Causal mediation analysis for stochastic interventions
  • Observational Methods: Learning from Data: G-methods and IPTW
  • Policy Evaluation: Continuous MTP grids, factor recodes, and survival LMTP (CausalTargeted)
  • Software Patterns: Four-package identify → estimate → display layout
  • Model Validation with Observable Data: Validating TMLE results